Preserving Complex Object-Centric Graph Structures to Improve Machine Learning Tasks in Process Mining
Abstract
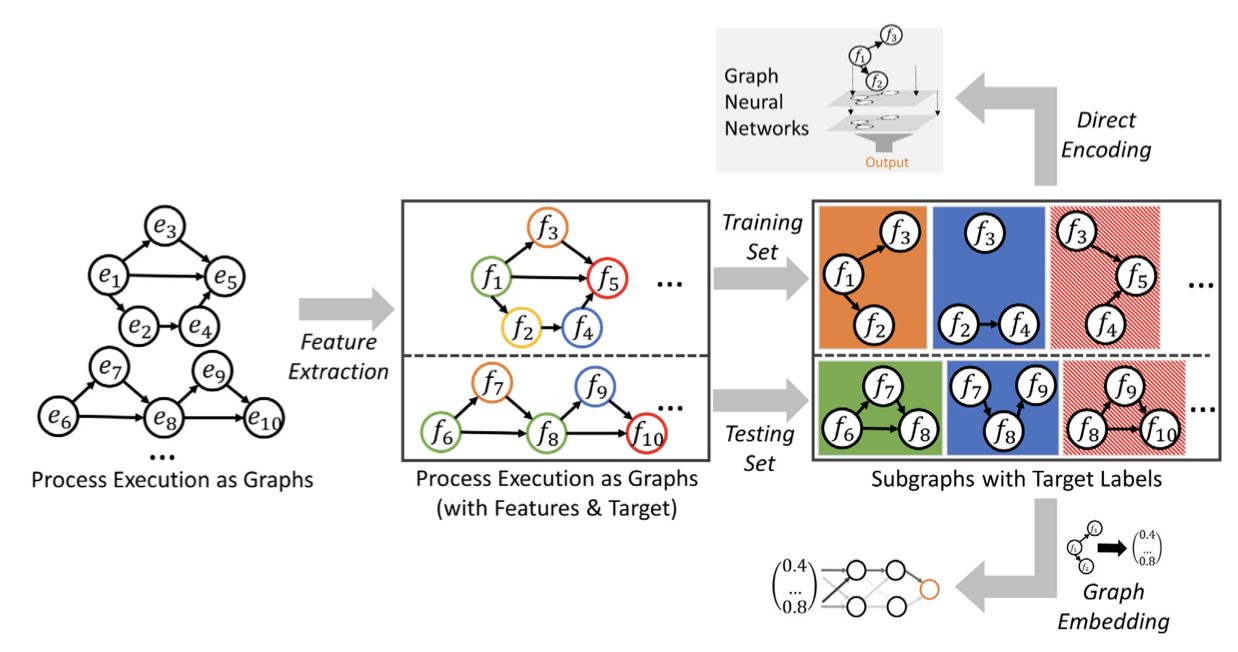
Interactions of multiple processes and different objects can be captured using object-centric event data. Object-centric event data represent process executions as event graphs of interacting objects. When applying machine learning techniques to object-centric event data, the event log has to be flattened into sequential process executions used as input for traditional process mining approaches. However, sequentializing the events by flattening removes the graph structure of object-centric event data and, therefore, constitutes an information loss. In this paper, we present a general approach to preserve the graph structures of object-centric event data across machine learning tasks in process mining. We provide two different techniques to preserve these structures depending on the required input format of machine learning techniques: as direct graph encodings or as graph embeddings. We evaluate our contributions by applying three different predictive process monitoring tasks to direct graph encodings, graph embeddings, and flattened event logs. Based on the relative performances, we assess the information contained in the graph structure of object-centric event logs that is, currently, lost in machine learning approaches for traditional process mining. Furthermore, we compare different graph embedding techniques for object-centric event logs to derive recommendations for future research and deployment. To conclude, we assess the improvement that graph embeddings constitute over state-of-the-art approaches that capture object information through specific features. Our contributions improve predictive process monitoring on object-centric event data and quantify the potential performance increases of predictive models. These contributions are especially relevant when looking at real-life applications of predictive process monitoring which are often applied to information systems with relational databases that contain multiple objects and, currently, still enforce flattening.
Practical problem
Companies run their processes on systems such as Enterprise Resource Planning (ERP) software, where one event typically touches several business objects at once: an order, its items, the deliveries and the invoices that belong to it. Analysts who want to predict how such a process will continue (what happens next, when, how long until completion) feed this data into machine-learning models that expect one neat sequence of events per case. Forcing the data into that shape, known as flattening, throws away how objects interact: rework on one object becomes indistinguishable from the same activity on a second object, the number of objects and their individual paths disappear, and an activity can no longer be tied to the object it belonged to. Existing attempts to repair this add a few hand-designed object counts as features, which recover only a small part of what was lost.
Research questions
- How much predictive information is lost when the graph structure of object-centric process executions is flattened into event sequences?
- What is the best way to preserve that graph structure for machine-learning applications in process mining?
Contributions
- A general approach that keeps object-centric process executions as event graphs throughout the machine-learning pipeline, either as direct graph input or as graph embeddings for vector-based models.
- Formalizes process executions as event graphs over connected components of the object graph, and flattening as a baseline transformation, with worked examples of three kinds of structural information loss.
- An end-to-end predictive pipeline (subgraph extraction, leakage-free train/test split, graph neural network or embedding plus regression/MLP) covering next activity, next timestamp and remaining time.
- An evaluation protocol that isolates the value of structure alone (no event features) and a benchmark that measures the added value of embeddings over state-of-the-art object-centric features.
- An implementation on top of the
ocpaPython library with experiments released on GitHub (niklasadams/PreservingOCStructures).
Key findings
- On the BPI Challenge 2017 loan-application log (507,553 events, 67,498 objects, 31,509 process executions), graph-based input beats the flattened baseline for every task and subgraph size k = 2 to 8; the gap usually grows with k.
- Averaged over the three prediction tasks, flattening loses structural information worth a 41.7% relative performance improvement with a graph neural network; the best embedding, Family of Graph Spectral Distance (FGSD), reaches 40.8%.
- Among seven graph embeddings, FGSD and GL2Vec perform best almost everywhere, NetLSD and Spectral Features worst; MLP slightly beats regression but the embedding choice matters more.
- Appended to state-of-the-art object-centric features, FGSD embeddings improve prediction by 2.43% on average across 147 models, and by 4.42% at the largest subgraph size k = 8.
- The structure alone carries little value for remaining-time prediction, and the results rest on only two event logs (one synthetic order-management log and one real-life log with two object types).